LINE Chatbot / Survey Design / Support Metrics
Fair CSAT: telling loan decisions apart from support problems
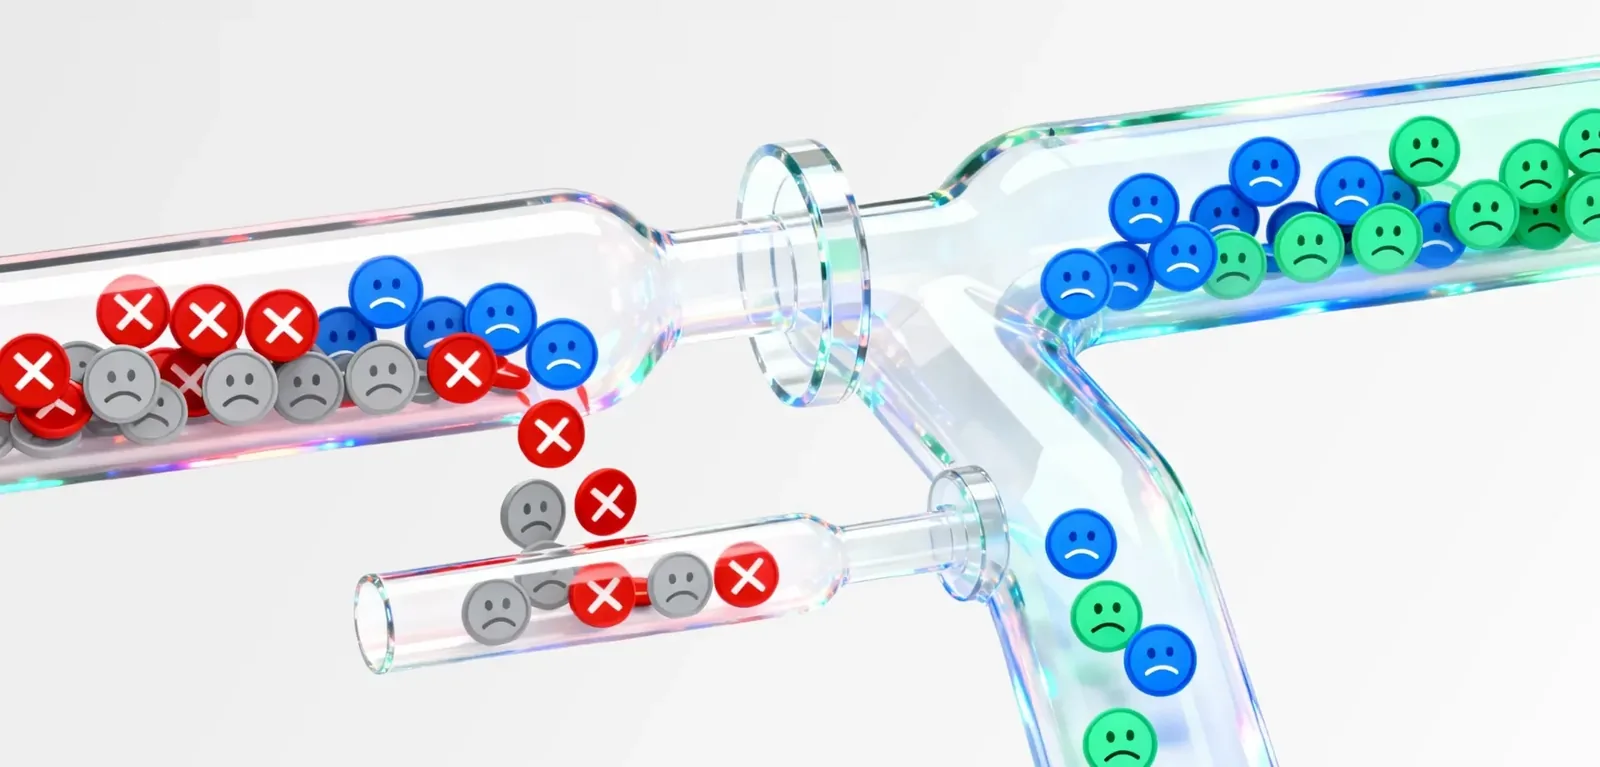
Overview
MoneyThunder is ABACUS Digital's lending app. After borrowers chat with the Customer Excellence team on LINE, they rate the help from 1 to 5 and can leave a comment. A 1 often had little to do with the help. It came from a loan decision: a rejection, or a smaller limit than they hoped for.
The project had two goals. Make CSAT measure the support the team gives, not how people feel about a loan decision. And stop the team spending hours every week reading comments it could do nothing about.
I led it as Head of Design: the four-question test, the follow-up flow and its wording, the four groups of unhappy customers, and the two scores we report. A chatbot developer built the survey into the LINE chatbot, and the Customer Excellence team runs the review.
- Role
- Head of Design, ABACUS Digital
- Team
- Me, a chatbot developer and the Customer Excellence team
- Time
- Since late 2024
- Outcome
- Support scored without loan-decision complaints, and review down from 2–3 hours a week to 1–2 a month
Why a 1 wasn't about support
Low scores mixed two kinds of pain. One was service friction the team could fix: an answer that wasn't clear, a fix that didn't work, getting stuck uploading documents. The other was a loan decision the team couldn't change. To find the first kind, someone read every comment and chat log, about two to three hours each week, and most of it turned out to be the second.
One question became four
First we split the single rating into four questions: the loan outcome, how well we solved the problem, how quickly, and how clearly we answered. The bet was simple. If the problem is the service, the loan outcome score stays high or neutral. If it is the decision, that score drops.
The pattern showed in the first week. Customers who gave the loan outcome a 1 were mostly the ones who had been turned down, and about 60% of them gave a 1 to all four questions. Their comments asked why they were rejected when their income was stable and their history clean. Service problems read differently: the answer wasn't clear, the fix didn't work, the upload got stuck.
A short follow-up instead
Four questions is a lot to ask after every chat. The survey we shipped asks one, and only asks more when someone is unhappy.
- Chat on LINEA borrower gets help from Customer Excellence
- Rate the help1 to 5. A 4 or 5 ends the survey
- Rate the loan outcomeAfter a 1 to 3. A 4 or 5 here points to the service
- What should we improve?After an outcome of 1 to 3. Three reasons to tap
- Service friction"Didn't answer my question" or "didn't solve my problem"Loan decision"Unhappy with the loan decision"
A service reason means the case is looked into, every time. The loan decision tags the response as decision-driven, kept apart from the service cases and reviewed once a month. When an answer is vague, we ask for detail or pass it to a person for a quick look.
Four groups of unhappy customers
The answers sort into four groups. Each one tells the team whether to look now, look once a month, or ask better questions.
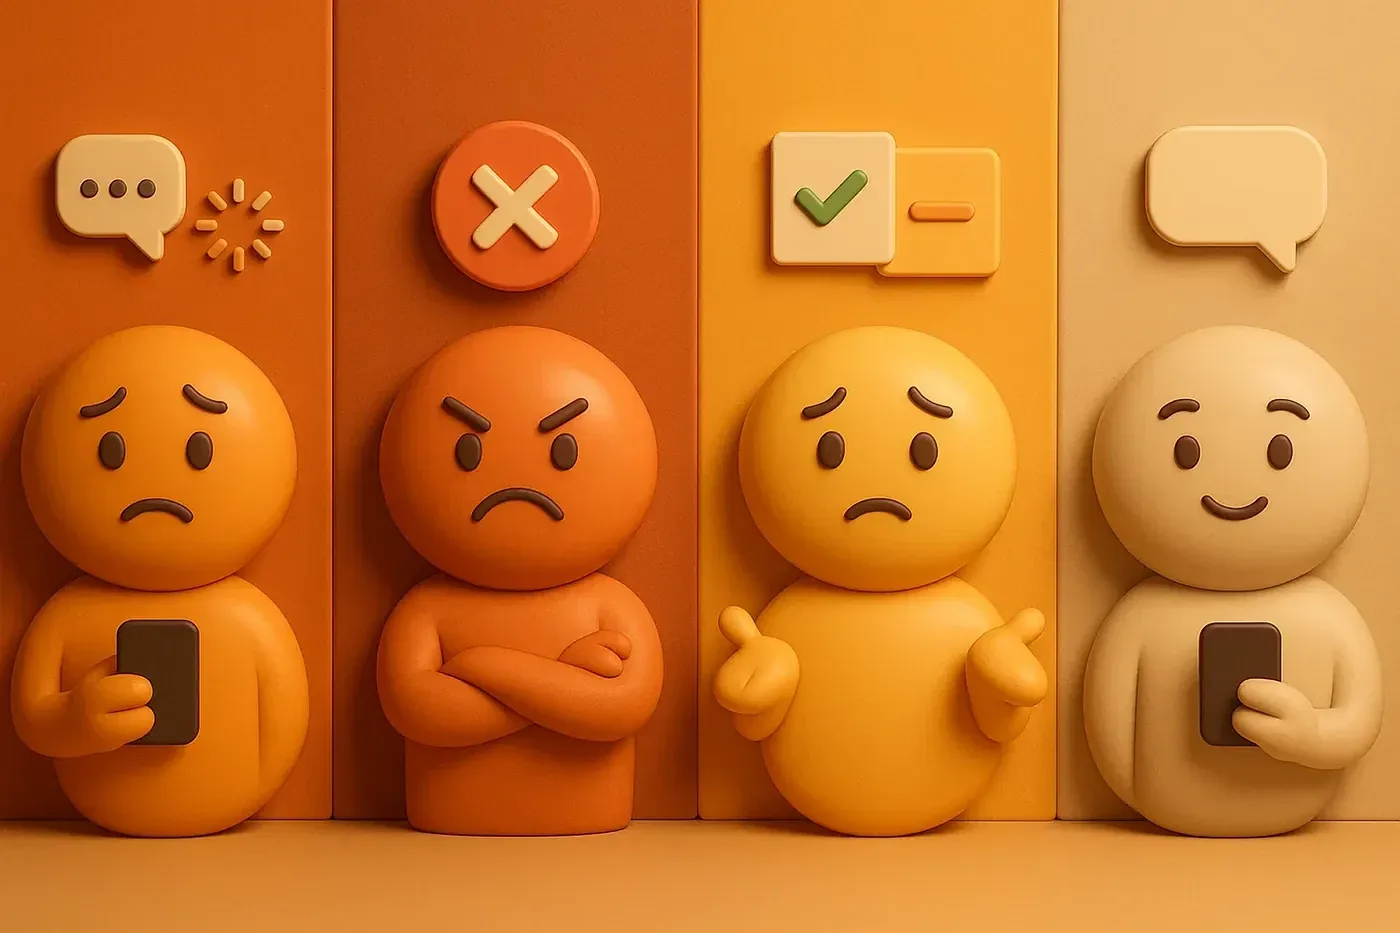
- Service friction. A low score for the help, while the loan outcome gets a 4 or 5, or "not sure". Comments like "the answer didn't help" or "still broken". Every case is traced through the chat, the screens and the handoff, and becomes a fix ticket.
- Outcome. A low loan outcome score and the loan decision as the reason. Kept separate and sampled monthly, to make the approval criteria and timelines clearer.
- Ambiguous. A low loan outcome score, with comments that mix unclear answers and anger at the decision. Sampled monthly and sorted into one of the first two.
- Low signal. A low score and no detail. Sampled monthly. These led to sharper questions and quick-tap reasons, so the next answer says more.
Two scores, so the numbers stay honest
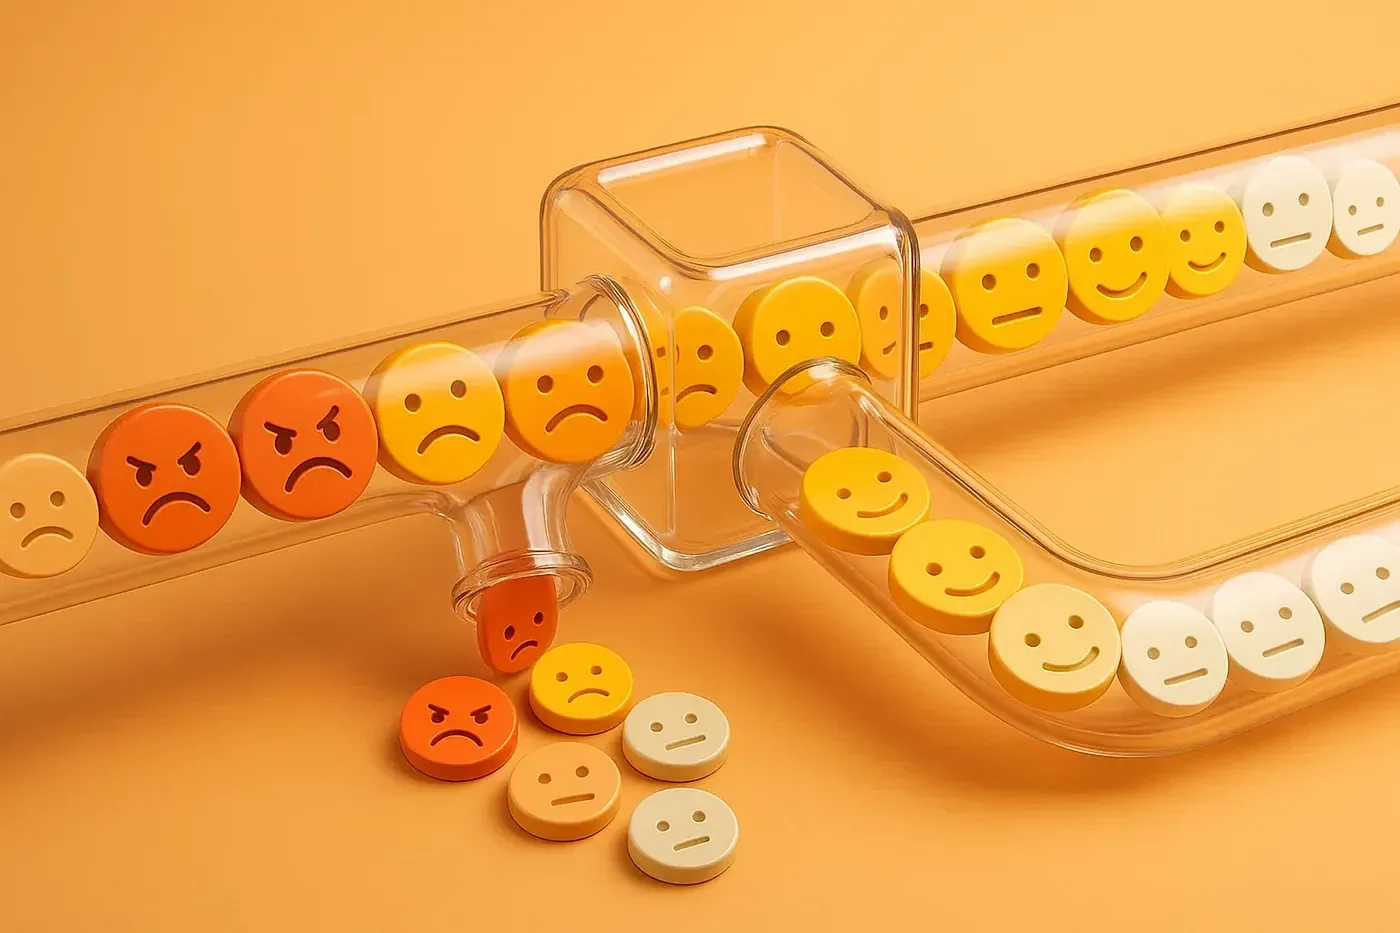
- Raw CSAT is the average of every response, service and outcome alike. It shows the overall mood.
- Adjusted CSAT leaves out the decision-driven responses. It is the fair read of support, and the main number on the team's dashboard.
We also track what share of unhappy responses comes from loan decisions. In leadership reports, the gap between Raw and Adjusted shows how much of the unhappiness is about the decision rather than the service.
Outcome
Support is now judged on Adjusted CSAT, so the team is no longer marked down for decisions it doesn't make.
The review got much smaller. Reading comments to find what could be fixed took about two to three hours every week. Now it is one or two hours once a month, for the monthly samples. Service friction cases are still looked into as they come in, and faster, because the borrower has already picked the reason. The time saved goes back into the team's other work.
What I took from it: read CSAT with its context. In lending, feelings about a loan decision spill into every score, and a small change to the survey was enough to pull them apart.