Analytics / Forecasting
Inventory Replenishment: data-driven stock control for a Thai kitchen in Melbourne
Overview
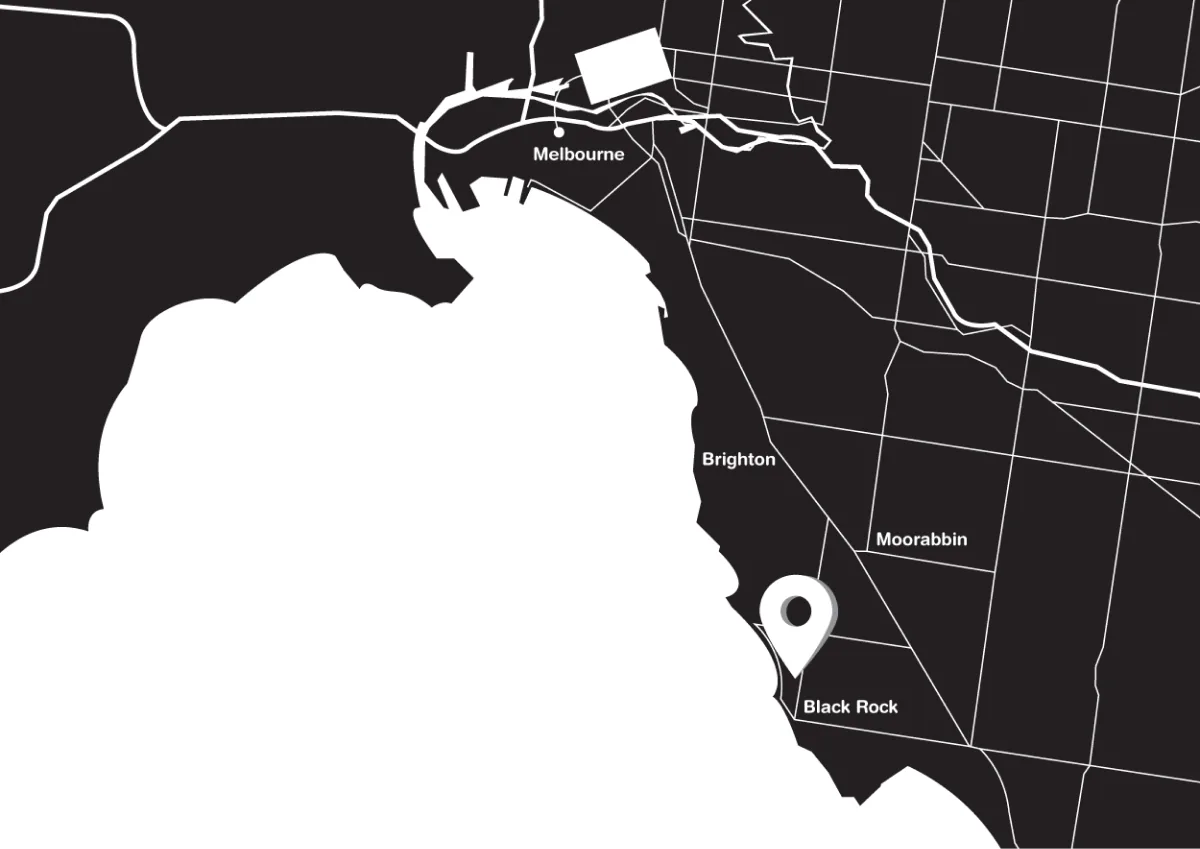
Bluff Kup Cafe & Thai Kitchen is an established restaurant in Melbourne (Figure 1) with steadily growing revenue. Its inventory was costly and hard to manage. I used business analytics on its point-of-sale (POS) sales data to recommend better ways to manage stock.
I did this as part of my master's in Supply Chain Management.
Inventory Issues
Inventory drives revenue in hospitality. Restaurants hold a lot of stock to keep the menu broad (Jung & Yoon 2012), and much of it is perishable. Food that expires unused is lost money and waste.
Ineffective Inventory Review Policy
Staff prefer to check stock at set times, because it doesn't need constant watching. Some ingredients still run out, and customers notice. Staff also pick reorder amounts by feel, which adds bias. A policy based on numbers is one option (Wisner et al., 2016).
Food Waste
Demand is hard to predict, so stock sits too long. Hygiene and safety rules still apply (Glanz et al., 2007), and some ingredients spoil before they're used. Predictive models and statistical methods can help with that uncertainty (Stefanovic 2014).
Data Collection & Preparation
Data Obtaining
FoodStory runs the restaurant's orders and inventory and records what staff do. The data sits in a relational database that can be queried with SQL. This report uses sales from January 2015 to December 2016. The first extract has six variables: _payment_id_, _create_date_, _menu_group_name_, _menu_name_, _price_, and _quantity_.
Data Cleaning
Cleaning started with a check for missing values. Over time the manager renamed some menu groups and dishes. _209 Green Chicken_, _602 Green Chick Curry_, and _702 Green Chick Curry_ are the same dish, so I renamed them by hand to _Green Chicken Curry_.
Additional Variables Adding
I then gave each dish a main ingredient. For example, _Chilli Fish_ and _Crispy Fish Salad_ each use one unit (200 grams) of _barramundi_. Adding up demand by ingredient instead of by dish gives a more accurate forecast (Chatfield 2016).
Data Analysis by R Programming
Pareto Principle
RevCon, a script I wrote in R, reads a folder of CSV files and returns each ingredient's share of sales and the running total (Code 1).
RevCon <- function(directory) {
# Import and merge file.csv from directory
files_list <- list.files(directory, full.names=TRUE)
no_of_files <- length(files_list)
Data.df <- data.frame()
for(h in 1:no_of_files) {
  Data.df <- rbind(Data.df, read.csv(files_list[h]))
}

# Change create_date to date format
Data.df[,2] <- as.Date(Data.df$create_date,
  format='%d/%m/%Y')

# Aggregate sales by invntories
Contri.df <- aggregate(price ~ main_ingredient,
  Data.df, sum)

# Calculate contribution in percentage
RevCon.df <- data.frame(Contri.df,
round(100*(Contri.df$price/
sum(Contri.df$price)),digits = 3))

colnames(RevCon.df)[1:3] <- c("Inventory","Total_Sales",
"Contribution")

# Sort contribution and calculate cumulative
RevCon.df <- RevCon.df[with(RevCon.df,
  order(-Contribution)), ]
RevCon.df <- data.frame(RevCon.df, cumsum(RevCon.df[,3]))
colnames(RevCon.df)[4] <- "Cumulative"

# Print results
RevCon.df
}
Demand Variability & Volatility
COV, also in R, calculates the mean, standard deviation, and coefficient of variation for each item. Before that, it smooths outliers with a five-period centered moving average (Code 2).
COV <- function(directory) {
  # Enable xts package
  library(xts)

# Import and merge file.csv from directory
files_list <- list.files(directory, full.names=TRUE)
no_of_files <- length(files_list)
Data.df <- data.frame()
for(h in 1:no_of_files) {
  Data.df <- rbind(Data.df, read.csv(files_list[h]))
}

# Change the type of object in main_ingredient and create_date
Data.df$main_ingredient <- as.character(Data.df$main_ingredient)
Data.df$create_date <- as.Date(Data.df$create_date,format='%d/%m/%Y')

# Create a list of distinct inventories
Inv_List <- unique(Data.df$main_ingredient)
Inv_List <- as.character(Inv_List)

# Create all dates to replace missing dates
All_dates = seq(as.Date(as.yearmon(min(Data.df$create_date))),
  as.Date(as.yearmon(max(Data.df$create_date))), by="day")

# Create emtry an data frame
Output <- data.frame()

# Calculate weekly means, SDs and COVs of individual ingredients
for (i in 1:length(Inv_List)){
  Menu_List <- subset(Data.df, main_ingredient == Inv_List[i])
  Menu_List[,2] <- as.Date(Menu_List$create_date,
format='%d/%m/%Y')
  Menu_List <- aggregate(quantity ~ create_date, Menu_List, sum)

  #Add missing dates
  Menu_List = merge(data.frame(date = All_dates), Menu_List,
by.x='date', by.y='create_date',
all.x=T, all.y=T)
  colnames(Menu_List)[1:2] <- c("create_date","quantity")
  Menu_List[is.na(Menu_List)] <- 0

  # Use xts package to aggregate daily into weekly demand
  Menu_List <- as.xts(Menu_List$quantity,order.by
=as.Date(Menu_List$create_date))
  Menu_List <- apply.weekly(Menu_List,sum)
  colnames(Menu_List)[1] <- "Weekly"

  # Calculate IQR to identify any outlier
  IQRs <- quantile(Menu_List$Weekly, prob = 0.75) -
quantile(Menu_List$Weekly, prob = 0.25)
  Lower <- quantile(Menu_List$Weekly, prob = 0.25) -
1.5*IQRs
  Upper <- quantile(Menu_List$Weekly, prob = 0.75) +
1.5*IQRs
  # Treat the outlier by applying 5-day centred moving average
  for (l in 1:length(Menu_List[,1])){
  if (Menu_List[l,1] < Lower) {
Menu_List[l,1] <- round(mean(Menu_List[l-2:l+2,1],
digits = 2))
  } else if (Menu_List[l,1] > Upper) {
Menu_List[l,1] <- round(mean(Menu_List[l-2:l+2,1],
digits = 2))
  } else if (Menu_List[l,1] == 0) {
Menu_List[l,1] <- 0
  } else {
Menu_List[l,1] <- Menu_List[l,1]
  }
}

  # Calculate weekly means, SDs and COVs of individual ingredients
  Menu_List <- data.frame(Inv_List[i],
round(mean(Menu_List), digits = 0),
round(sd(Menu_List), digits = 0),
round(100*(sd(Menu_List)/mean(Menu_List)),
  digits = 2))

  # Add the results to data frame
  Output <- rbind(Output, Menu_List)
}

# Rename columns
colnames(Output)[1:4] <- c("Inventory","Weekly Avg.","SD","COV")

# Sort ascending COV
Output <- Output[with(Output, order(COV)), ]

# Print the result
Output
}
Recommendations
Inventory Segmentation
ABC analysis groups items by impact. Class A has a high impact on income or volatile demand. Classes B and C have lower impact and steadier demand. Table 3 shows the result. Class A is checked daily or twice a week, Class B at the end of each week, and Class C monthly, so staff spend less time watching every item (Muckstadt & Sapra 2010).
- Class A: Chicken, Prawn, Beef, Pork belly, Duck, Beer, White wine, Jasmine rice, Corkage, Barramundi, Mix of entrée, Roti, Calamari, Red wine, Salmon, Scallop
- Class B: Lamb, Cabbage, Soft shell crab, Coconut rice, Soft Drink, Potato, Coffee, Vegetable
- Class C: Brown rice, Thai dessert, Ice cream, Sparkling wine, Papaya, Pork, Quail, Tofu, Liqueur, Sparkling water, Satay sauce, Tea, Golden bag, Rose wine, Champagne, Chocolate, Pumpkin cake, Crispy ruby, Sticky rice, Cake
Inventory Review Policy
One policy doesn't fit items with different value and volatility (Bartmann & Bach 2012). Class A gets continuous review: staff keep stock above the reorder point every day. Classes B and C stay on periodic review, weekly or monthly. The reorder point uses this equation (Wisner et al. 2016):
ROP = Mean + (Z value + Standard Deviation)
For chicken, the reorder point is 187 units, from average demand of 142 units and a standard deviation of 27 units per week during lead time (Table 2). With a 95% cycle service level, the Z value is 1.64. So the manager reorders when chicken drops below 28 kg (1 unit = 0.15 kg), which covers 95% of weekly demand while the next delivery is on its way.
Discussion and Conclusion
The approach has two limits. The data needs regular updates (Shumway & Stoffer 2010), and storage space is limited (Dye et al., 2007), so a calculated reorder point won't always fit the kitchen. Judgment still matters. The numbers support decisions; they don't make them (Runkler 2012).
Using the restaurant's own sales history, the study recommends statistical review policies, a data-driven culture, and clear methods staff can follow. Demand doesn't depend on time alone; other factors also shape what people choose to eat.
References
Bartmann, D & Bach, M F 2012, *Inventory control: models and methods*, Springer Science & Business Media, Germany.
Chatfield, C 2016, ‘Some More Advanced Topics’, *The analysis of time series: an introduction*, CRC press, USA, pp.255276.
Dye, C Y, Ouyang, L Y & Hsieh, T P 2007, ‘Deterministic inventory model for deteriorating items with capacity constraint and timeproportional backlogging rate’, *European Journal of Operational Research*, vol. 178, no. 3, pp.789807.
Glanz, K, Resnicow, K, Seymour, J, Hoy, K, Stewart, H, Lyons, M & Goldberg, J 2007, ‘How major restaurant chains plan their menus: the role of profit, demand, and health’, *American journal of preventive medicine*, vol. 32, no. 5, pp.383388.
Jung, H S & Yoon, H H 2012, ‘Why do satisfied customers switch? Focus on the restaurant patron varietyseeking orientation and purchase decision involvement’, *International Journal of Hospitality Management*, vol. 31, no. 3, pp.875884.
Muckstadt, J A & Sapra, A 2010, ‘Inventories Are Everywhere’, *Principles of inventory management: When you are down to four, order more*, New York: Springer, USA.
Runkler, T A 2012, *Data Analytics Models and Algorithms for Intelligent Data Analysis*, Vieweg+Teubner Verlag, Germany.
Shumway, R H & Stoffer, D S 2010, ‘Characteristics of Time Series’, *Time series analysis and its applications: with R examples*, Springer Science & Business Media, USA.
Stefanovic, N 2014, ‘Proactive supply chain performance management with predictive analytics’, *The Scientific World Journal*, vol. 2014.
Wisner, J D, Tan, K C & Leong, G K 2016, ‘Inventory Management’, *Principles of Supply Chain Management: A Balanced Approach*, 4th Edition, Cengage Learning, USA, pp.207246.